Started training my 256 images on FLUX with 8x GPU - Dataset is not ready yet, not very good sharpness and lightning but so many people asking expressions so i am taking a break from research :) - Going up to 200 epochs I also wonder results
FLUX Training With 256 Images Started on 8x GPU
FLUX training with a massive 256-image dataset started on an 8x GPU machine and goes up to 200 epochs, because many people asked for more expressions.
A short progress note: the dataset is not ready yet and has weak sharpness and lighting, so this run is a break from the research to see what 256 images can do.

Related
All Research postsFLUX LoRA Training With 256 Images: Full Workflow & Conclusions
FLUX LoRA training experiments with 256 images on 8x A6000 and 1x L40S GPUs: 80 epochs worked best, and doubling the learning rate for 8 GPUs overtrained.
Qwen Image 2512 Training Comparison: The Best Model to Train
Qwen Image 2512 is the new king for training: the video compares trained Base, 2512, Edit 2509 and Edit 2511 models and shows a big leap in realism.
Qwen Image LoRA Training: Stage 1 Results and Pre-Made Configs
Qwen Image LoRA results from more than 35 Stage 1 trainings with SECourses Musubi Tuner; the published pre-made configs train on GPUs with as low as 6 GB.
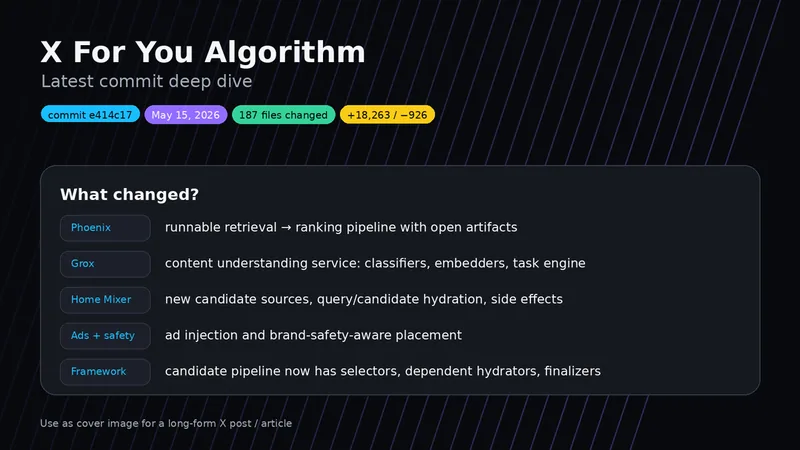
X Algorithm Update: Deep Dive Into the Latest x-algorithm Commit
X's For You recommendation algorithm got a bigger update than it looks: commit e414c17 changed 187 files with 18,263 additions across the feed stack.
BF16 vs GGUF Q8 vs FP8 Scaled vs NVFP4: Quality and Speed Comparison
BF16, GGUF Q8, FP8 Scaled and NVFP4 precisions compared for speed and quality in ComfyUI with CUDA 13; NVFP4 ran 87% faster than GGUF Q8 on Z Image Turbo.
NVFP4 With CUDA 13 Tutorial: 100%+ Speed Gain & Quality Comparison
NVFP4 models run over 100% faster in ComfyUI and SwarmUI with CUDA 13; this full tutorial compares NVFP4 quality on FLUX 2, Z Image Turbo and FLUX 1 in grids.