Research, Comparisons and Experiments
Our own measured comparisons, benchmarks and training experiments: models, precisions, GPUs, trainers and settings, with full results.
X Algorithm Update: Deep Dive Into the Latest x-algorithm Commit
X's For You recommendation algorithm got a bigger update than it looks: commit e414c17 changed 187 files with 18,263 additions across the feed stack.
BF16 vs GGUF Q8 vs FP8 Scaled vs NVFP4: Quality and Speed Comparison
BF16, GGUF Q8, FP8 Scaled and NVFP4 precisions compared for speed and quality in ComfyUI with CUDA 13; NVFP4 ran 87% faster than GGUF Q8 on Z Image Turbo.
NVFP4 With CUDA 13 Tutorial: 100%+ Speed Gain & Quality Comparison
NVFP4 models run over 100% faster in ComfyUI and SwarmUI with CUDA 13; this full tutorial compares NVFP4 quality on FLUX 2, Z Image Turbo and FLUX 1 in grids.
Qwen Image 2512 Training Comparison: The Best Model to Train
Qwen Image 2512 is the new king for training: the video compares trained Base, 2512, Edit 2509 and Edit 2511 models and shows a big leap in realism.
Qwen Image 2512 First Training: 120 vs 180 vs 240 Epochs Comparison
Qwen Image 2512 first training results: the model behaves like FLUX Dev, and more training makes it more realistic with less noise on a 28-image dataset.
FLUX 2 vs FLUX SRPO & New Kohya SS GUI Premium FLUX Training App
FLUX 2 Pro compared with a trained FLUX SRPO model, plus the new Kohya trainer V35 that trains FLUX on GPUs with as little as 6 GB VRAM.
Qwen Image vs FLUX SRPO Training Comparison: 20 Images, Same Dataset
Qwen Image base model vs FLUX SRPO training on the same 28-image dataset: 20 side-by-side results show Qwen far ahead at complex prompts and emotions.
Qwen Image LoRA Training: Stage 1 Results and Pre-Made Configs
Qwen Image LoRA results from more than 35 Stage 1 trainings with SECourses Musubi Tuner; the published pre-made configs train on GPUs with as low as 6 GB.
Nano Banana (Gemini 2.5 Flash Image) vs Qwen Image Edit: Full Tutorial
Nano Banana image editing tested live in 27 unique cases against the free, local Qwen Image Edit, with every prompt, image and result shown in the tutorial.
Decoding the Timestep Shift in Diffusion Training: Qwen Image & FLUX
Timestep sampling shift explained for diffusion models: Qwen Image uses an exponential shift and FLUX a linear one, and 2.205 matches Qwen at 1664x928.
Qwen Image vs FLUX Dev vs FLUX Krea: New Text-to-Image King Comparison
Qwen Image compared with FLUX Dev and FLUX Krea over 700 generations; Qwen follows prompts far better and has a 68% bigger native resolution than FLUX Dev.
Kohya vs OneTrainer for FLUX Dev Fine-Tuning / DreamBooth: Comparison
Kohya and OneTrainer compared for FLUX Dev fine-tuning: OneTrainer with EMA and a copied Kohya config gave weaker results than the best Kohya config.
RTX 5090 vs RTX 3090 Ti Speed Test: FLUX Dev, SD 3.5, SDXL & SD 1.5
RTX 5090 benchmarked against RTX 3090 Ti on FLUX Dev, FLUX Fill, SD 3.5 Large and Medium, SDXL and SD 1.5 in SwarmUI with ComfyUI, on an AMD 9950X CPU.
MSI RTX 5090 Trio FurMark Benchmark, Overclock & Noise Test vs 3090 Ti
MSI RTX 5090 32G Gaming Trio OC review: FurMark benchmarks before and after overclocking, compared with a Gainward RTX 3090 Ti Phantom in the same PC.
FLUX Fine-Tuning / DreamBooth Images: 2x Latent Upscale, 2048x2048
FLUX fine-tuning / DreamBooth images made with a simple prompt and 2x latent upscale; each is 2048x2048 and training works on as low as 6 GB GPUs.
FLUX Fine-Tuning vs LoRA: Example Dataset, Trained Models & Configs
FLUX fine-tuning / DreamBooth vs LoRA experiment shared in full: a 28-image dataset, Kohya configs, grids and every trained checkpoint free on Hugging Face.
FLUX De-Distilled Fine-Tuning & LoRA Tests: Bleeding and CFG Results
FLUX de-distilled models train best at guidance scale 3.5 instead of 1, yet these DreamBooth and LoRA experiments show they still do not fix bleeding.
SD 3.5 Large vs FLUX Dev: Best Sampler, Scheduler & FP8 Comparison
Stable Diffusion 3.5 Large tested with 62 prompts to find the best sampler and scheduler, plus an SD 3.5 Large vs FLUX Dev comparison with raw grids shared.
FLUX LoRA vs Fine Tuning / DreamBooth Comparison: Batch Size 1 vs 7
FLUX LoRA and Fine Tuning / DreamBooth compared with 15 and 256 training images at batch size 1 and 7, for both realism and stylization.
Multi-GPU FLUX Full Fine-Tuning Test on RunPod: 2x A100 80 GB Results
Multi-GPU FLUX full fine-tuning / DreamBooth on 2x A100 80 GB GPUs gave only a 26% speed gain over one GPU, so 2x GPU training is not worth it yet.
FLUX LoRA Single Block Training Research: Network Alpha & Rank Tests
FLUX LoRA single block / layer training tested in Kohya GUI: one block needed over 10 times the usual learning rate and still gave sub-par results.
FLUX Full Fine Tuning vs LoRA Comparison: Less Overfitting & Bleeding
FLUX full fine tuning / DreamBooth gives way better results than LoRA training, as expected, with much less overfitting and bleeding.
FLUX LoRA Trained on 256 Images of Myself: Mind-Blowing Results
FLUX LoRA trained with Kohya GUI on 256 phone photos of myself, including the Clip-L and T5-XXL text encoders; it learned body shape and fine facial details.
FLUX LoRA Training With 256 Images: Full Workflow & Conclusions
FLUX LoRA training experiments with 256 images on 8x A6000 and 1x L40S GPUs: 80 epochs worked best, and doubling the learning rate for 8 GPUs overtrained.
Kohya FLUX LoRA Training Experiments: All 104 Trainings Listed
FLUX LoRA training experiments run with Kohya on an 8x RTX A6000 RunPod machine, 3000 steps each, with every trained model listed and shared on Hugging Face.
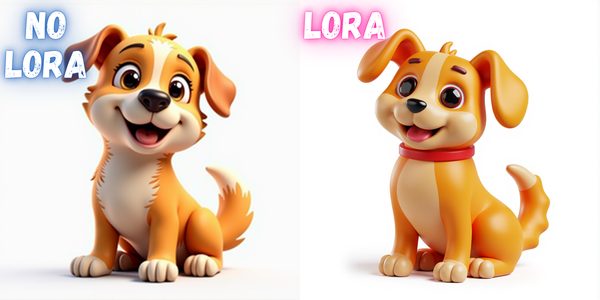
SECourses 3D Render Style FLUX LoRA Published on CivitAI
SECourses 3D Render FLUX LoRA model achieves style consistency; download it on CivitAI and get the full workflow with experiment results on Hugging Face.
FLUX LoRA Upscale Comparison: Raw vs SwarmUI 2x vs SUPIR App
FLUX LoRA output upscale comparison on an imgsli slider: the raw image vs the SwarmUI quick 2x upscale button vs our SUPIR app with face upscale on.
Training a Public FLUX Style LoRA: Captions vs No Captions Test
FLUX style LoRA training in public: captions vs no captions on a 114-image 3D render dataset, 500 epochs on 4x A6000 GPUs with Kohya.
FLUX Models Speed & VRAM Comparison: Every Version and Precision
FLUX Dev and Schnell in FP16, FP8 and NF4 compared for peak VRAM usage and speed in SwarmUI on an A6000; flux1-dev-fp8 uses 19.33 GB and takes 28 seconds.
SDXL Fine Tuning: 20 New OneTrainer Tests, Results and Better Workflow
SDXL fine tuning with OneTrainer on RealVis XL 4: 20 tests compare batch sizes, learning rates, xFormers, regularization images and loss weight functions.
SDXL Training: AdamW Batch Size 30 vs Adafactor Batch Size 1 Comparison
SDXL training test on an RTX A6000: AdamW at batch size 30 vs the SECourses Adafactor config at batch size 1, which gave far better resemblance.
DPM++ 2M SDE vs 3M SDE Sampler Test: Uniform vs Karras vs Exponential
DPM++ 2M SDE and DPM++ 3M SDE compared with Uniform, Karras and Exponential schedules on an SDXL DreamBooth model; DPM++ 3M SDE Uniform was the favorite.
SDXL DreamBooth Captioning Comparison: WD14 vs Kosmos-2 vs Ohwx Man
Image captioning in SDXL fine-tuning / DreamBooth of a single person reduces likeness with almost no benefit, in this OneTrainer test using 10.3 GB VRAM.
Video tutorials


