I did a test for one of our supporters. Used one of my older quite a bit overtrained DreamBooth model
Extracted LoRA as you can see yields almost perfect quality. Yes subtly changed but you can get quality with more generations
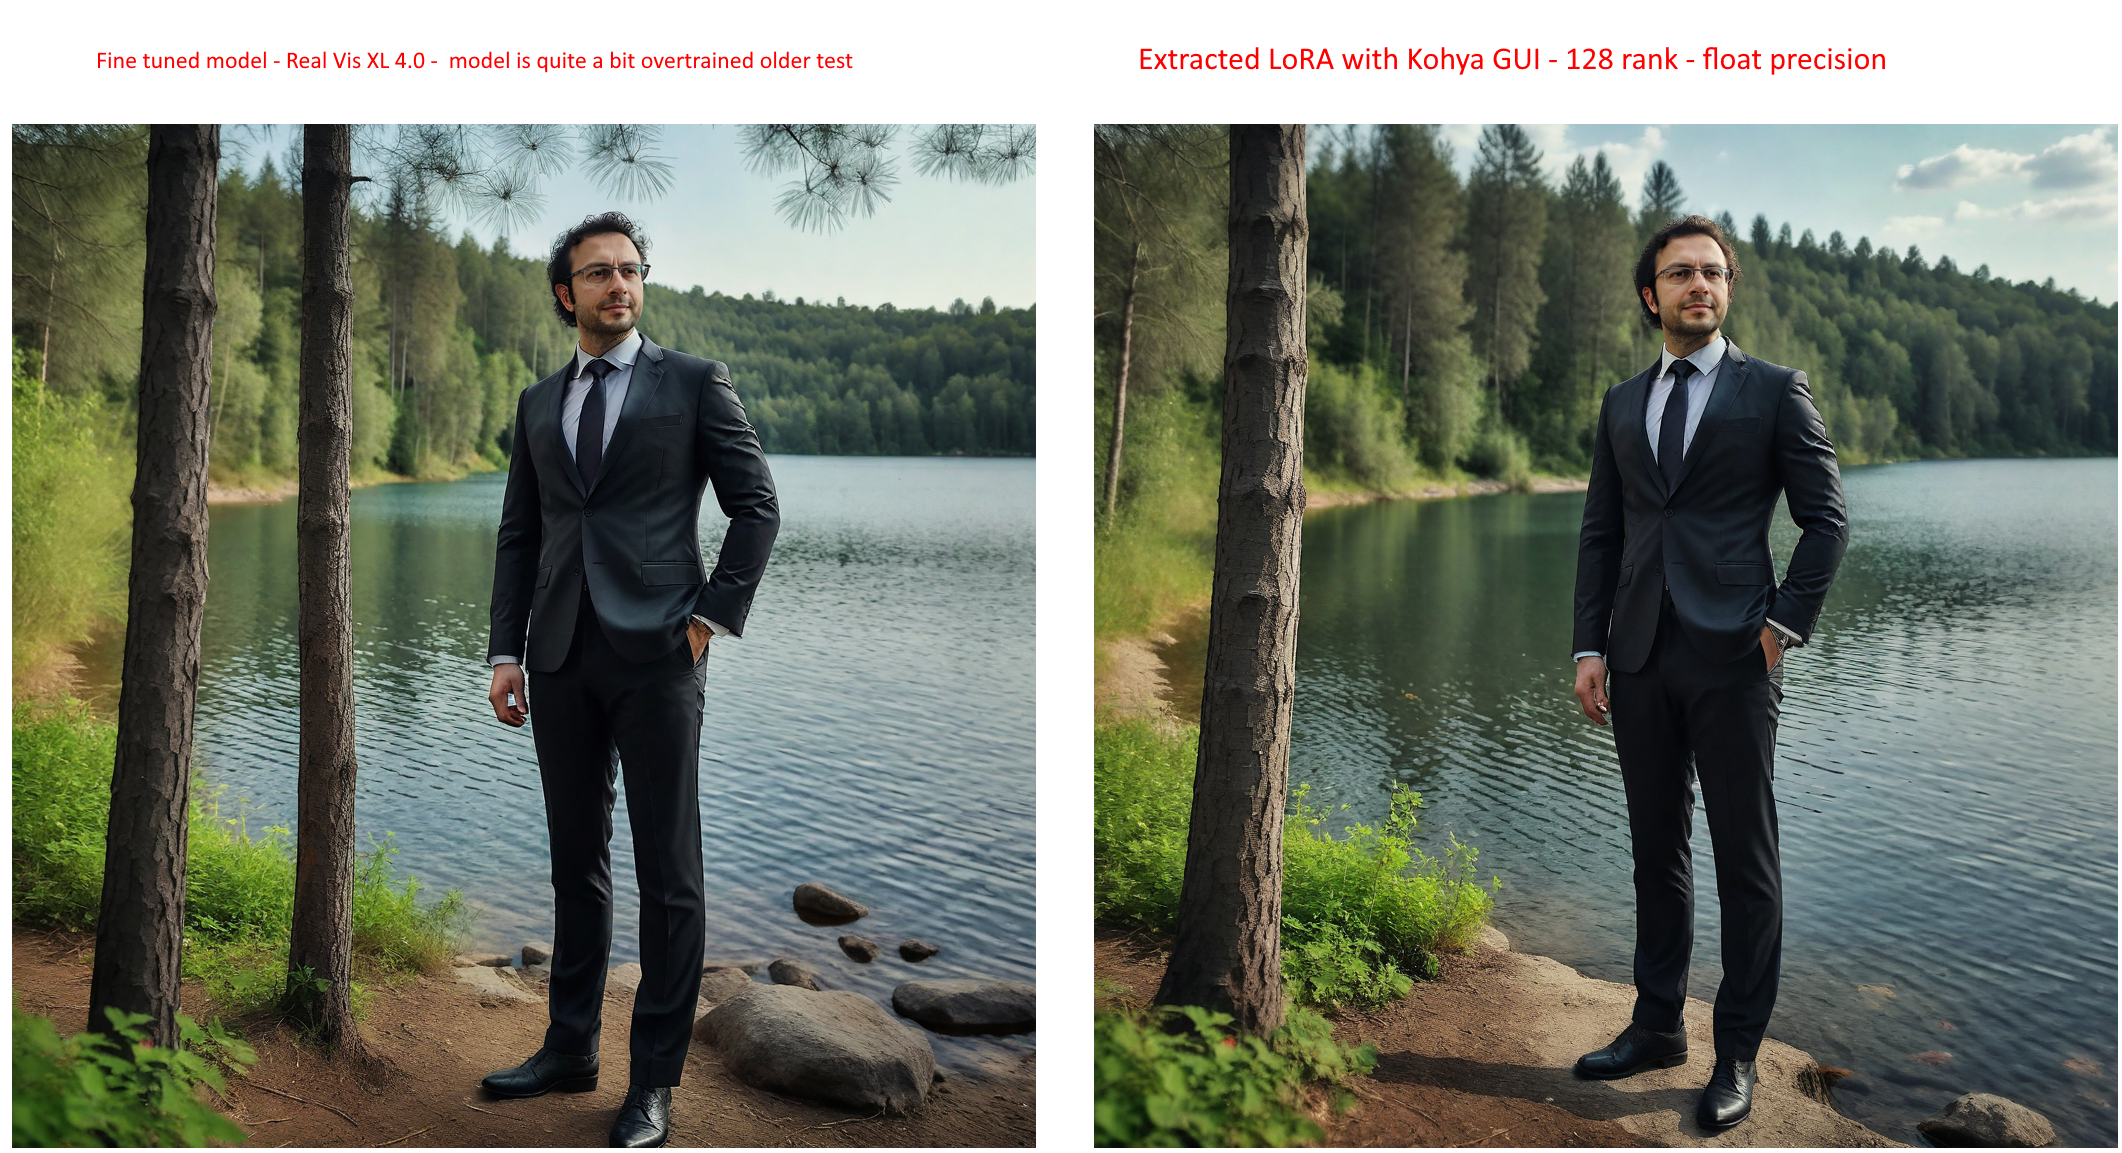
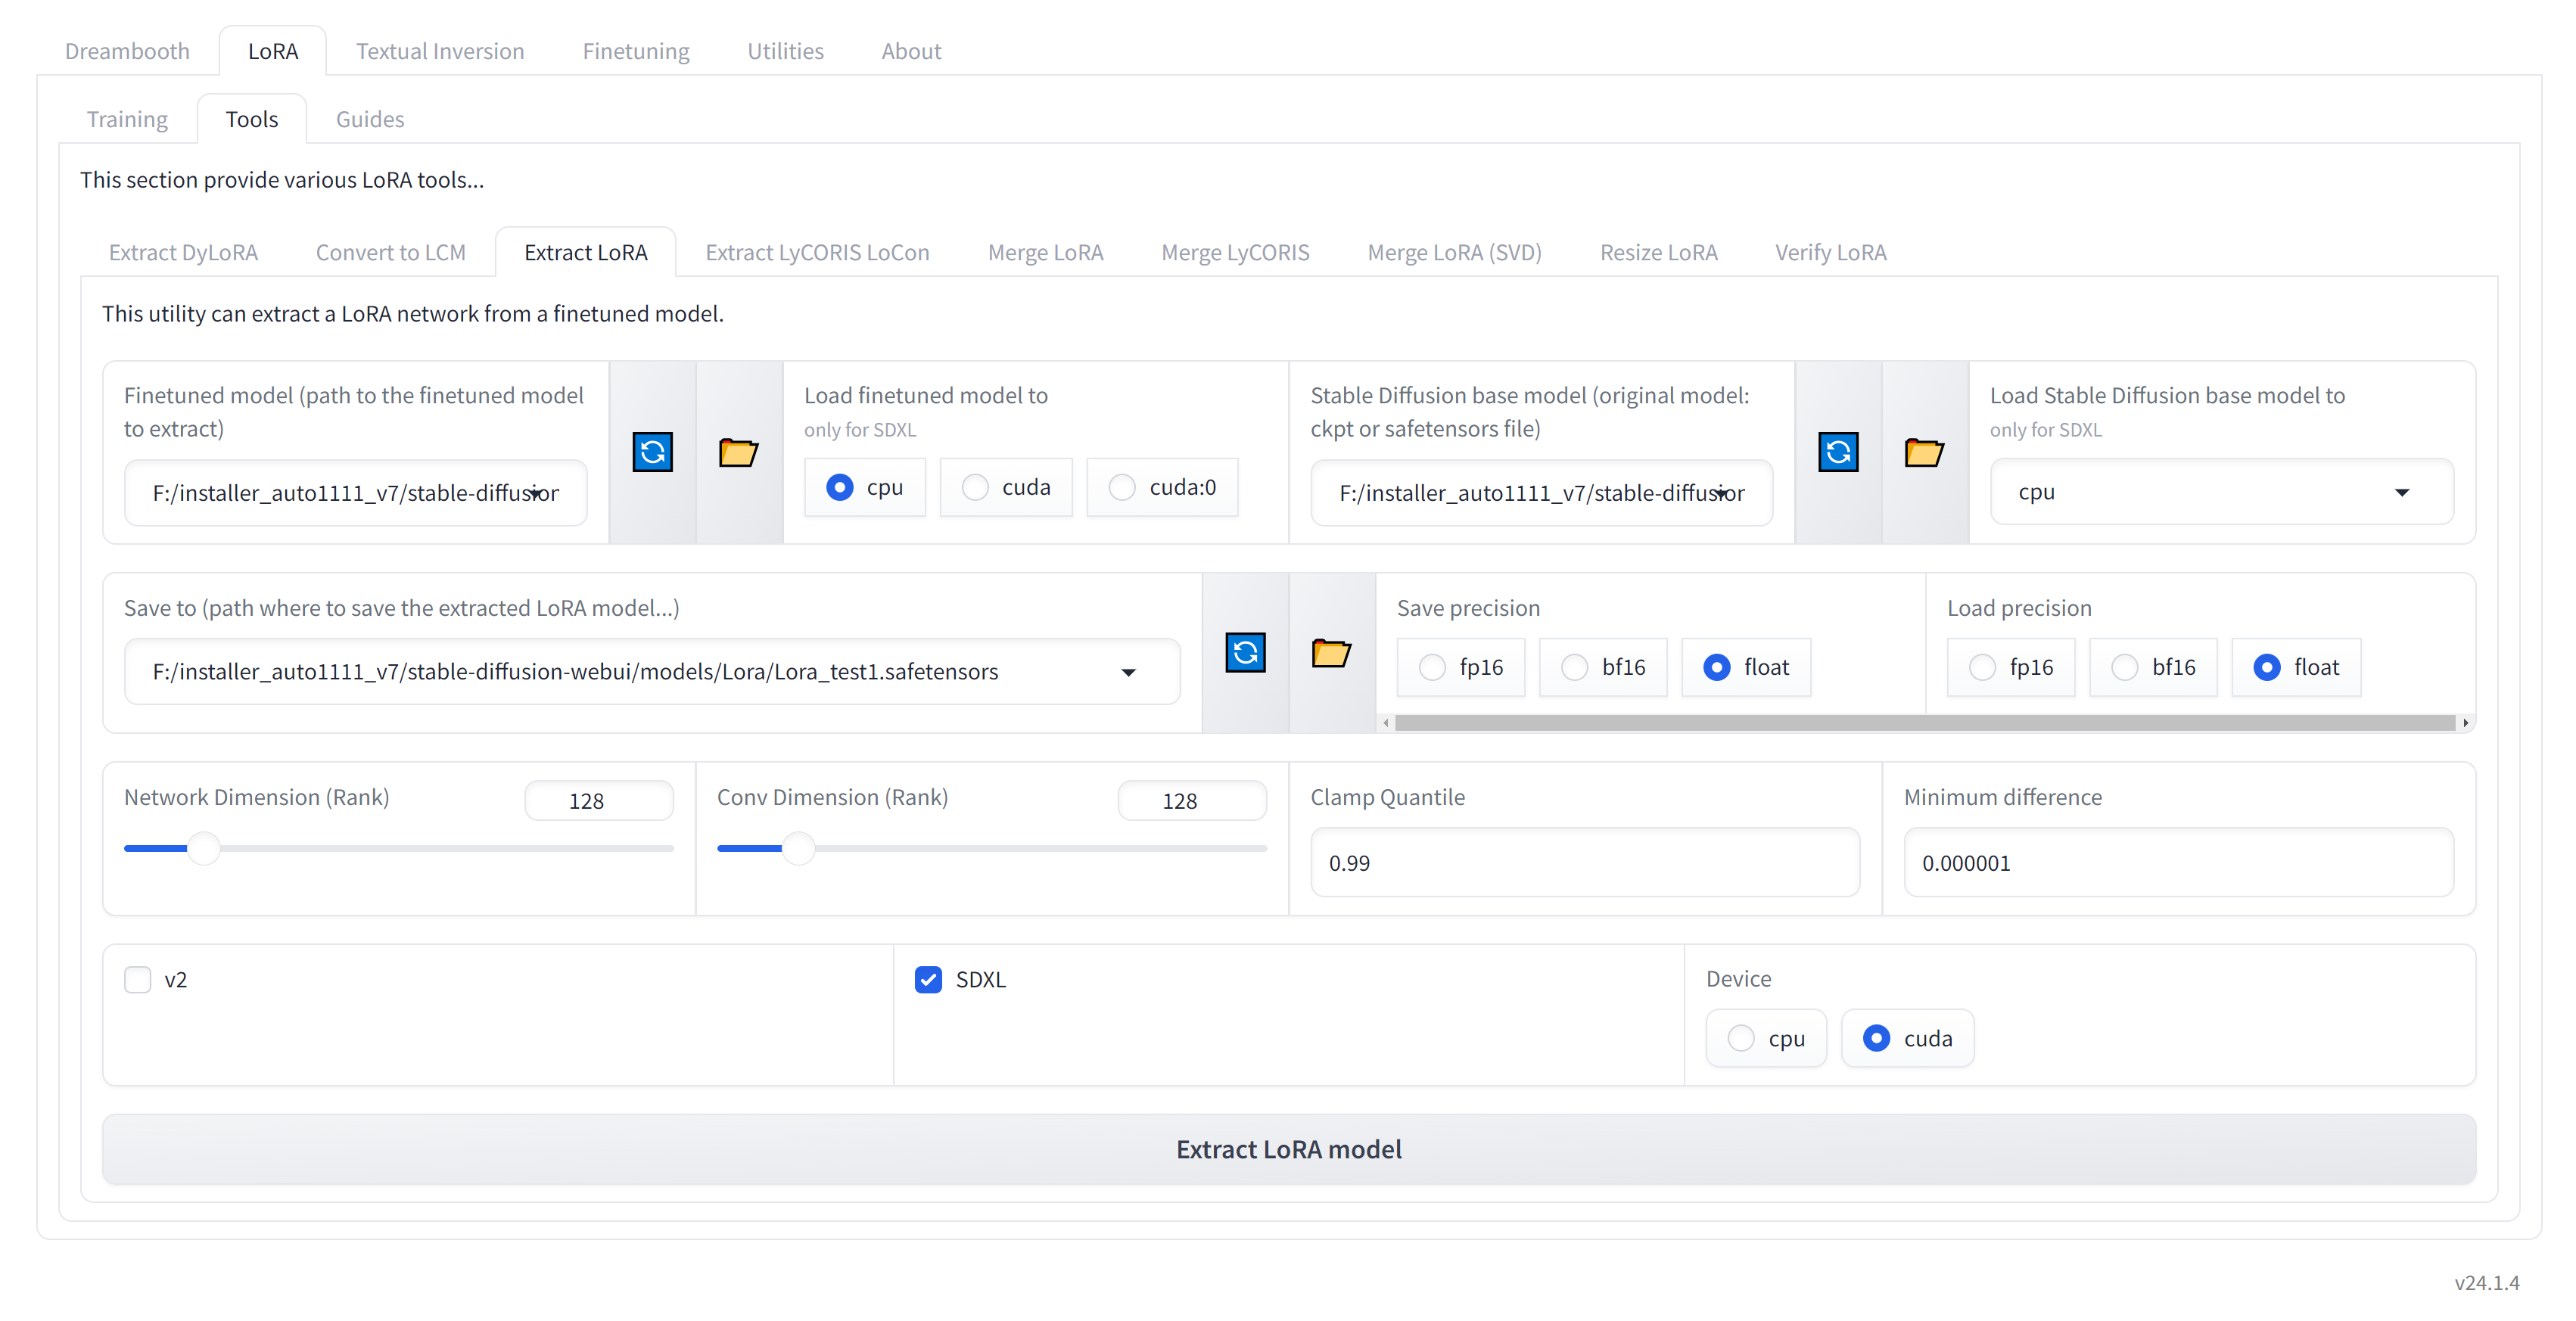
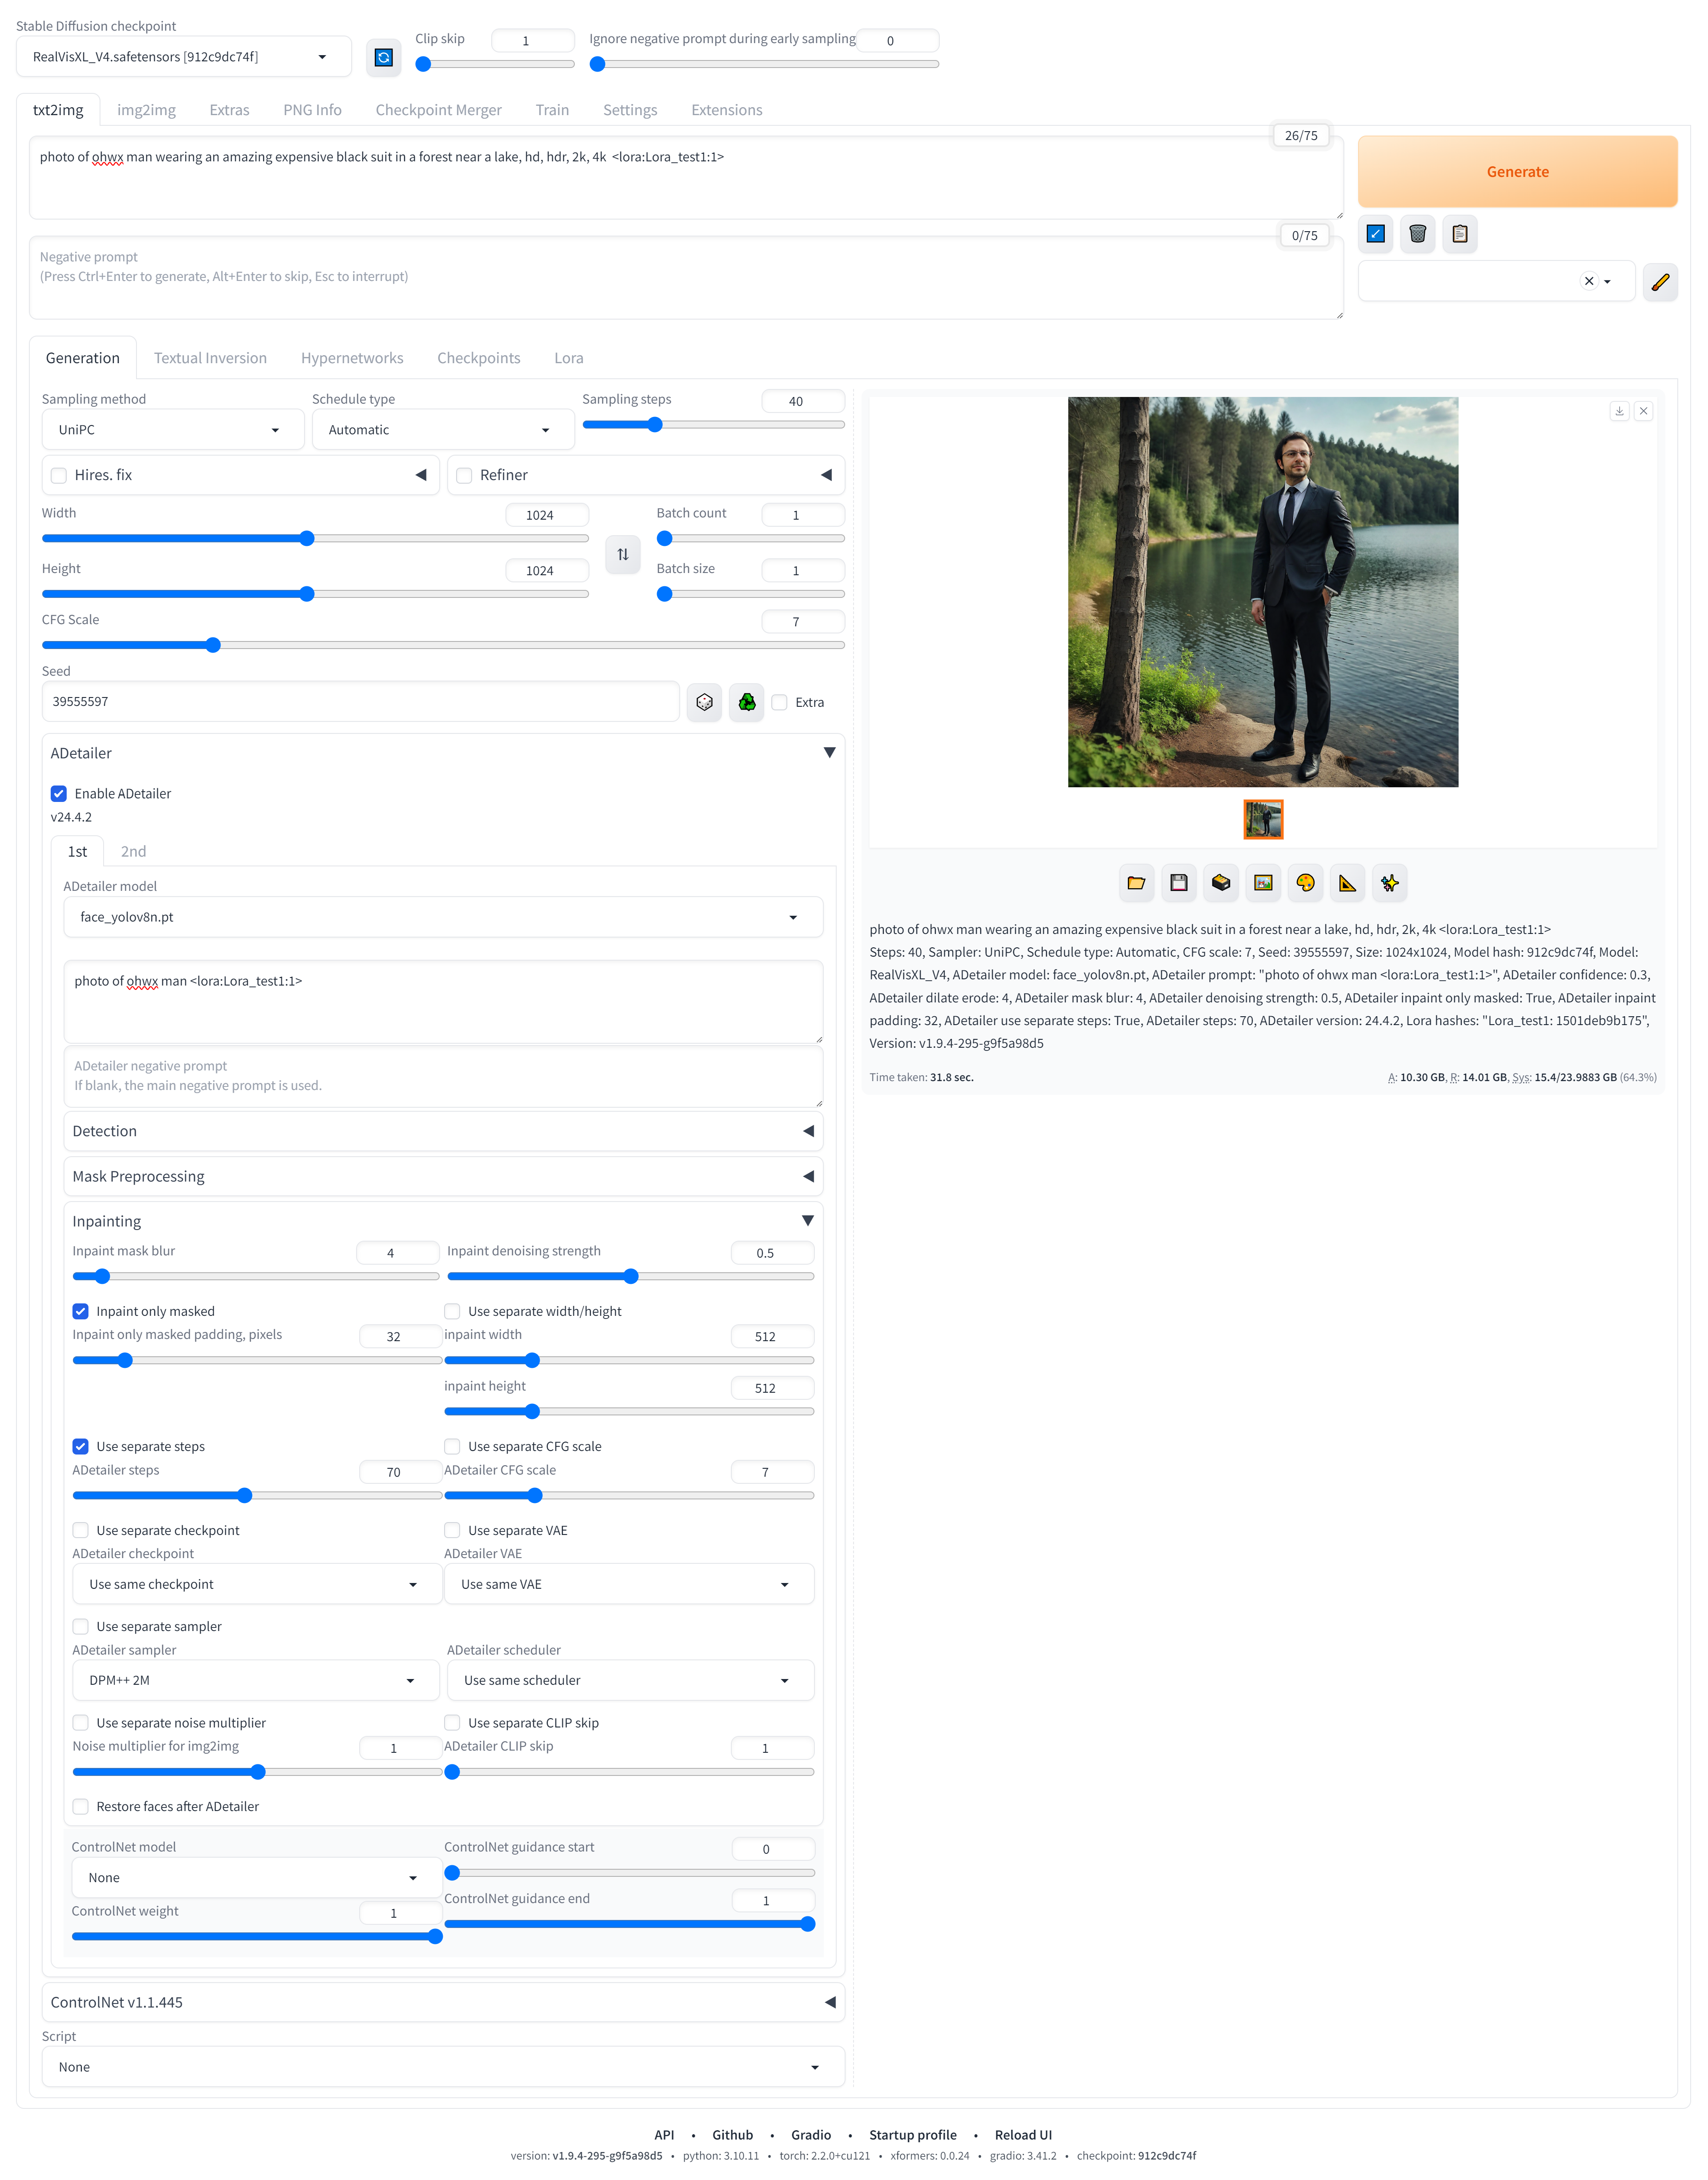
Extracted LoRA quick test: a LoRA extracted from an older, quite overtrained DreamBooth model keeps almost perfect quality, with only subtle changes.
Done for one of our supporters; the LoRA extract config and the Automatic1111 settings used for the test are shared as screenshots. More generations help you get back the original quality.

I did a test for one of our supporters. Used one of my older quite a bit overtrained DreamBooth model
Extracted LoRA as you can see yields almost perfect quality. Yes subtly changed but you can get quality with more generations

LoRA extraction from FLUX and SDXL DreamBooth models in Kohya, compared with fine tuning and LoRA training; higher ranks, up to 640, give better results.
Qwen Image 2512 is the new king for training: the video compares trained Base, 2512, Edit 2509 and Edit 2511 models and shows a big leap in realism.
FLUX 2 Pro compared with a trained FLUX SRPO model, plus the new Kohya trainer V35 that trains FLUX on GPUs with as little as 6 GB VRAM.
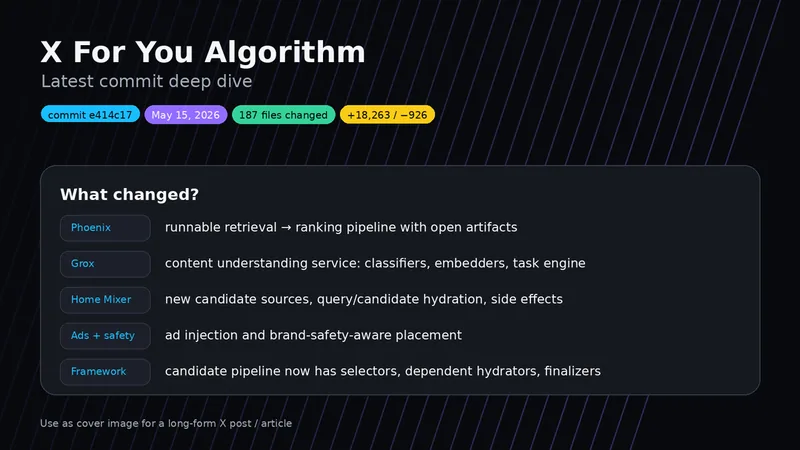
X's For You recommendation algorithm got a bigger update than it looks: commit e414c17 changed 187 files with 18,263 additions across the feed stack.
BF16, GGUF Q8, FP8 Scaled and NVFP4 precisions compared for speed and quality in ComfyUI with CUDA 13; NVFP4 ran 87% faster than GGUF Q8 on Z Image Turbo.
NVFP4 models run over 100% faster in ComfyUI and SwarmUI with CUDA 13; this full tutorial compares NVFP4 quality on FLUX 2, Z Image Turbo and FLUX 1 in grids.