On this page
Hunyuan3D-1 - SOTA Open Source Text-to-3D and Image-to-3D - 1-Click Install and use both Locally on Windows and on Cloud - RunPod and Massed Compute
Installers are here : Hunyuan3D-1 1-Click Installers: Text to 3D & Image to 3D Generation
Automatic Installers
- Works amazing on 24 GB GPUs
- Files > Hunyuan3D-1 1-Click Installers: Text to 3D & Image to 3D Generation
So what is Hunyuan3D-1
Official repo : https://github.com/tencent/Hunyuan3D-1
Tencent Hunyuan3D-1.0: A Unified Framework for Text-to-3D and Image-to-3D Generation
Abstract
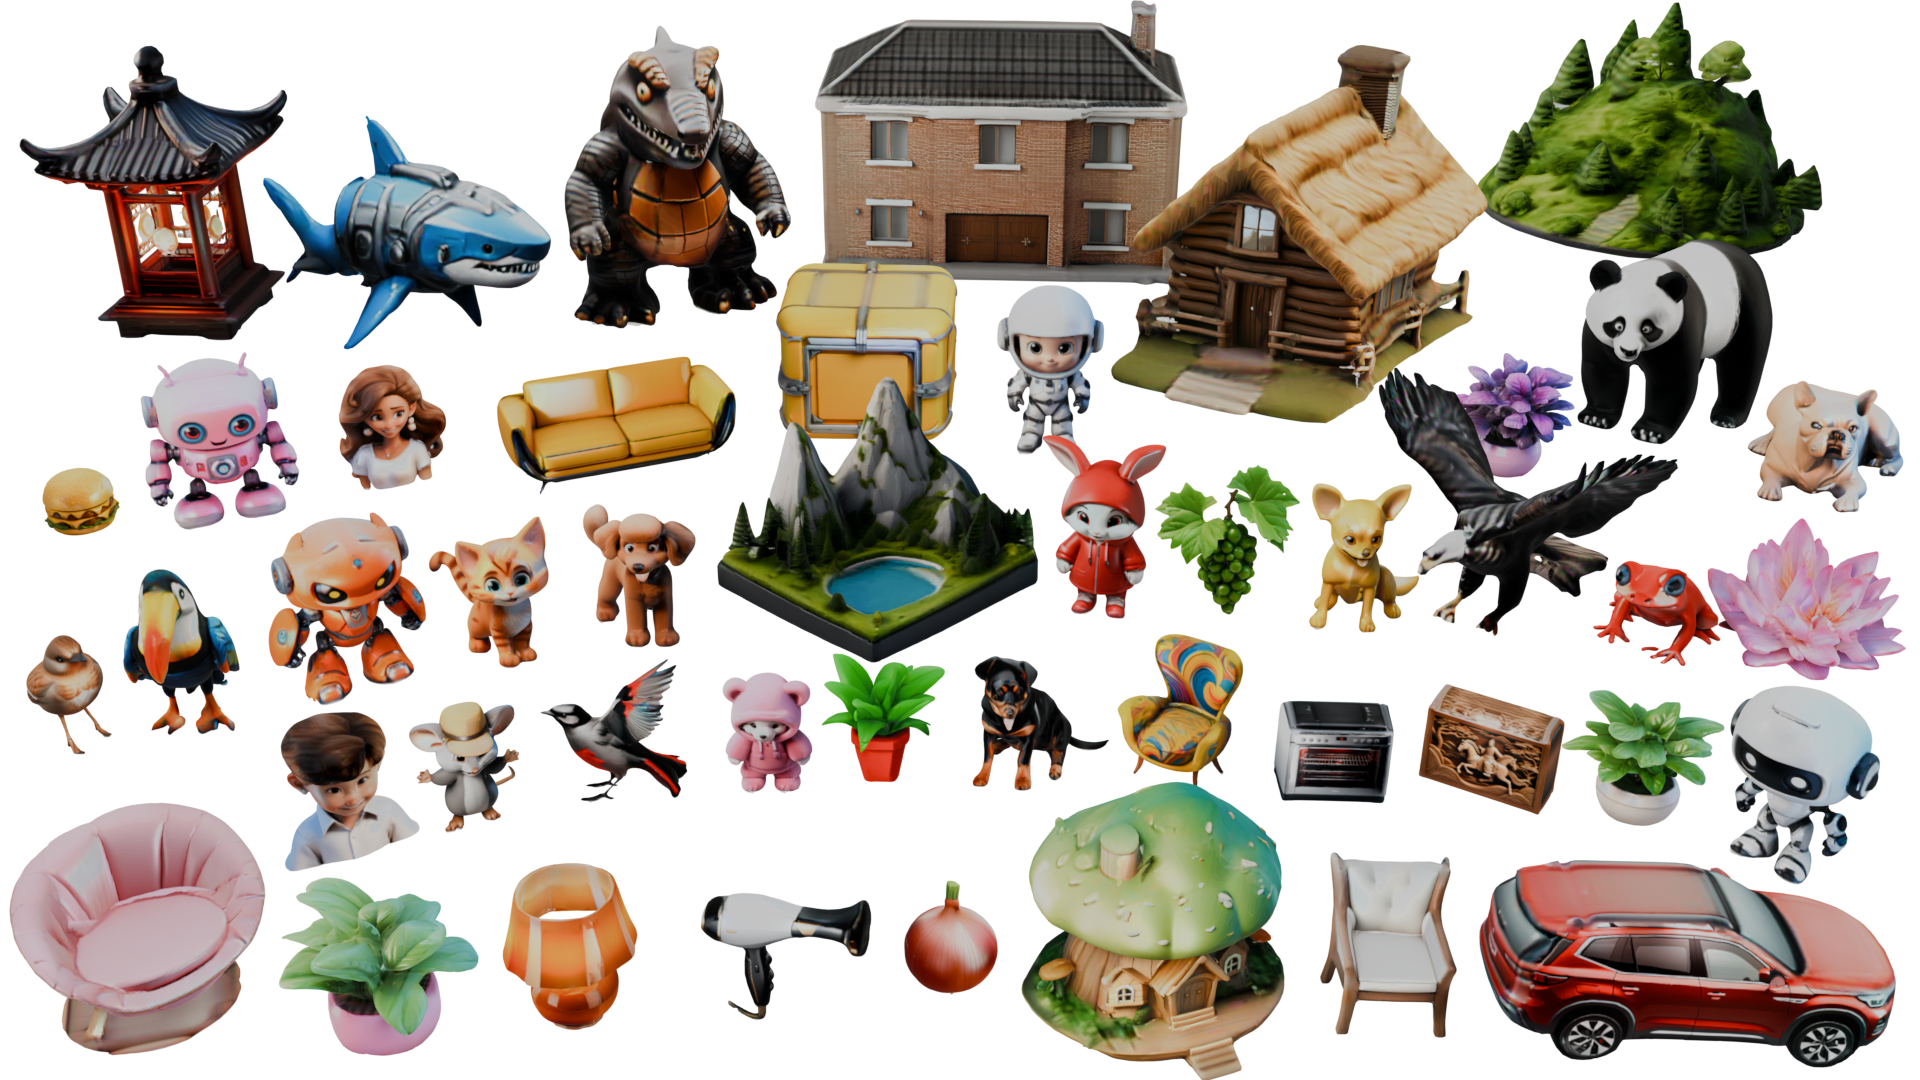
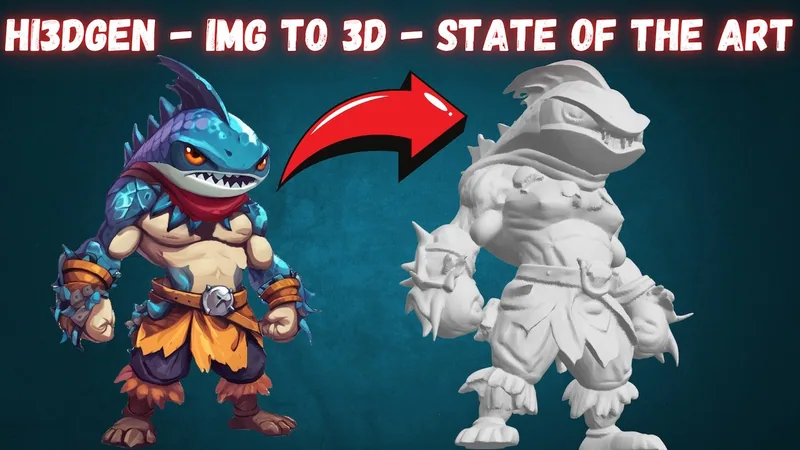
While 3D generative models have greatly improved artists' workflows, the existing diffusion models for 3D generation suffer from slow generation and poor generalization. To address this issue, we propose a two-stage approach named Hunyuan3D-1.0 including a lite version and a standard version, that both support text- and image-conditioned generation.
In the first stage, we employ a multi-view diffusion model that efficiently generates multi-view RGB in approximately 4 seconds. These multi-view images capture rich details of the 3D asset from different viewpoints, relaxing the tasks from single-view to multi-view reconstruction. In the second stage, we introduce a feed-forward reconstruction model that rapidly and faithfully reconstructs the 3D asset given the generated multi-view images in approximately 7 seconds. The reconstruction network learns to handle noises and in-consistency introduced by the multi-view diffusion and leverages the available information from the condition image to efficiently recover the 3D structure.
Our framework involves the text-to-image model, i.e., Hunyuan-DiT, making it a unified framework to support both text- and image-conditioned 3D generation. Our standard version has 3x more parameters than our lite and other existing model. Our Hunyuan3D-1.0 achieves an impressive balance between speed and quality, significantly reducing generation time while maintaining the quality and diversity of the produced assets.